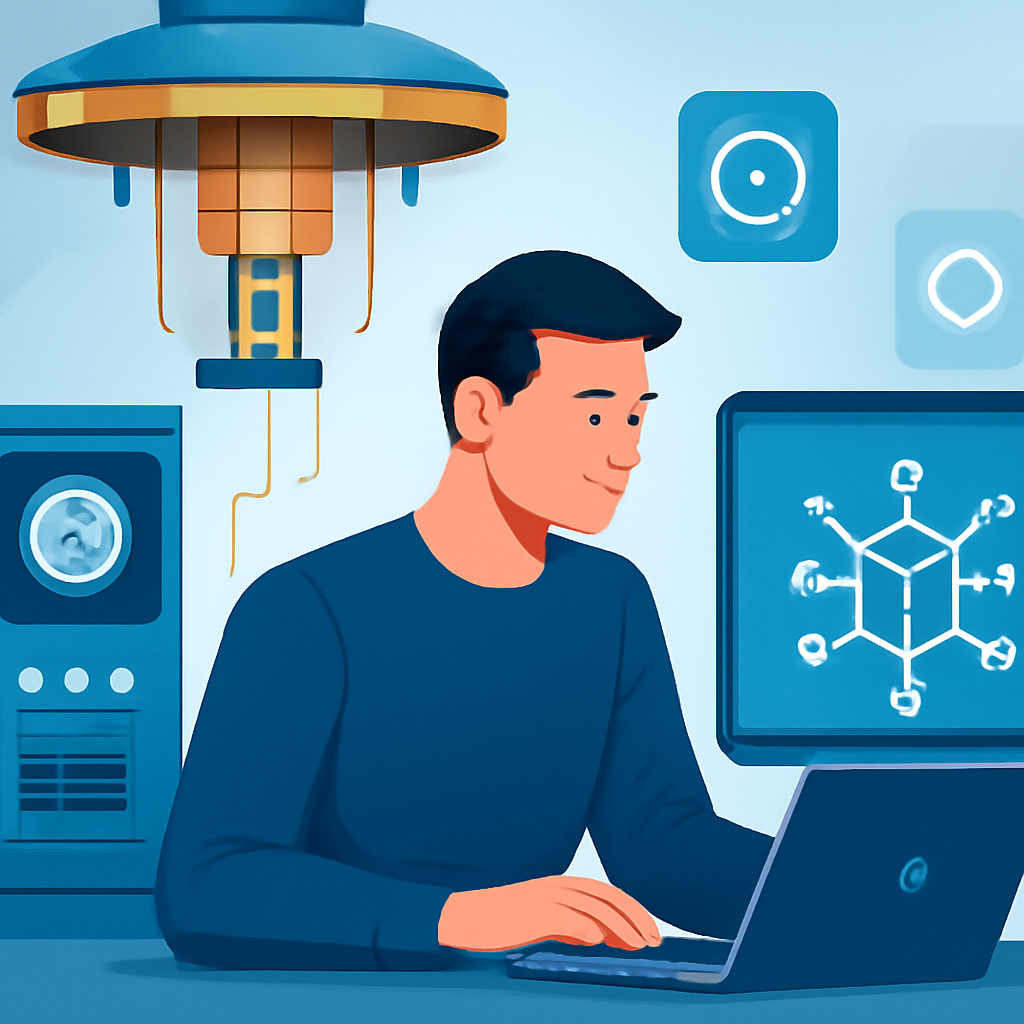
Researchers in MIT’s Engineering Quantum Systems Group (EQuS) tested whether GPT-5.6 Sol could be paired with Codex and integrated into laboratory control software to streamline the labor-intensive process of characterizing superconducting qubits. GPT-5.6 Sol was configured to select measurement parameters, run hardware operations through Codex, analyze returned signals and iterate when necessary — all within software-driven experimental workflows that are typical for qubit calibration and benchmarking.
Superconducting qubits are fabricated on chips, cooled in dilution refrigerators and controlled with precisely timed microwave pulses. Fully characterizing a chip is a multi-step process: identifying resonance frequencies, calibrating control and readout pulses, and measuring coherence times. Each of these steps produces results that inform the next, and drift or unexpected physical effects can require adaptive choices from an experienced experimentalist. The EQuS team chose this measurement-heavy workflow as a practical testbed for agent-driven automation.
In the deployed setup, Codex served as the bridge between the AI agent and the laboratory orchestration software. The researchers supplied measurement-specific skills describing how to run and evaluate individual routines along with the chip’s design targets. Using that information, GPT-5.6 Sol selected initial parameters, commanded the hardware, and processed the returned signals. When signals were clear, the agent routinely completed standard calibration sequences with minimal human oversight, identifying qubit transition frequencies, calibrating control and readout pulses, and measuring how long qubits retained quantum information.
On a six-qubit chip used by the group for fabrication benchmarks, the agent handled routine characterization across many steps. For well-defined, unambiguous measurements it iterated parameter choices until it converged on acceptable values and recorded results for subsequent stages. When measurement signals were strong and well behaved, the system reduced the need for continuous hands-on monitoring and allowed experiments to proceed for extended periods, including overnight.
However, the evaluation also highlighted limitations. In cases where signals were weak, noisy or otherwise ambiguous, GPT-5.6 Sol took longer to converge on suitable parameters and sometimes required intervention from an experienced researcher. The team concluded that agents perform well on clearly defined workflows but still face challenges when interpreting ambiguous physical data or responding to unexpected device behavior. As a result, human oversight remains essential for non-routine conditions and novel experimental goals.
The practical benefit reported by the MIT researchers was primarily a reallocation of researcher time. By delegating repetitive or time-consuming measurement tasks to the agent, experimenters could focus on higher-level activities such as interpreting results, designing follow-up experiments and writing new control, analysis or simulation code. For more novel objectives, the team used Codex agents with narrower tasks and relied on their ability to generate and test new code against live measurements, while keeping researchers in the loop for judgment calls.
EQuS fabricates many standard chips used for benchmarking and characterizing fabrication processes, each of which can require days to fully characterize. Automating routine calibration and analysis enables the group to redirect human effort toward complex problems, theory development and troubleshooting. The deployment demonstrates that software-controllable hardware, repeated measurements and adaptive decision-making make qubit calibration a natural testbed for AI-driven automation.
The MIT evaluation makes clear that AI agents like GPT-5.6 Sol can significantly reduce monitoring overhead for well-specified experimental procedures, but they are not a substitute for experienced researchers. Agents are effective at executing and iterating standard routines, yet they depend on human expertise when signals are unclear or experiments deviate from expectations. By combining agent-driven automation with human oversight, the EQuS team has shown a pragmatic path to accelerating device characterization while preserving the researcher’s role in interpretation and innovation.
As labs seek to scale fabrication and characterization workflows, the EQuS results suggest a hybrid model: let agents manage routine, long-running measurements and let humans concentrate on the creative, diagnostic and conceptual work that remains beyond current automation capabilities. The approach can shorten turnaround on standard tasks without removing the critical human judgment needed for advancing quantum experiments.
Source: Read the original source
Leave a Reply